What Is a Data Lake?
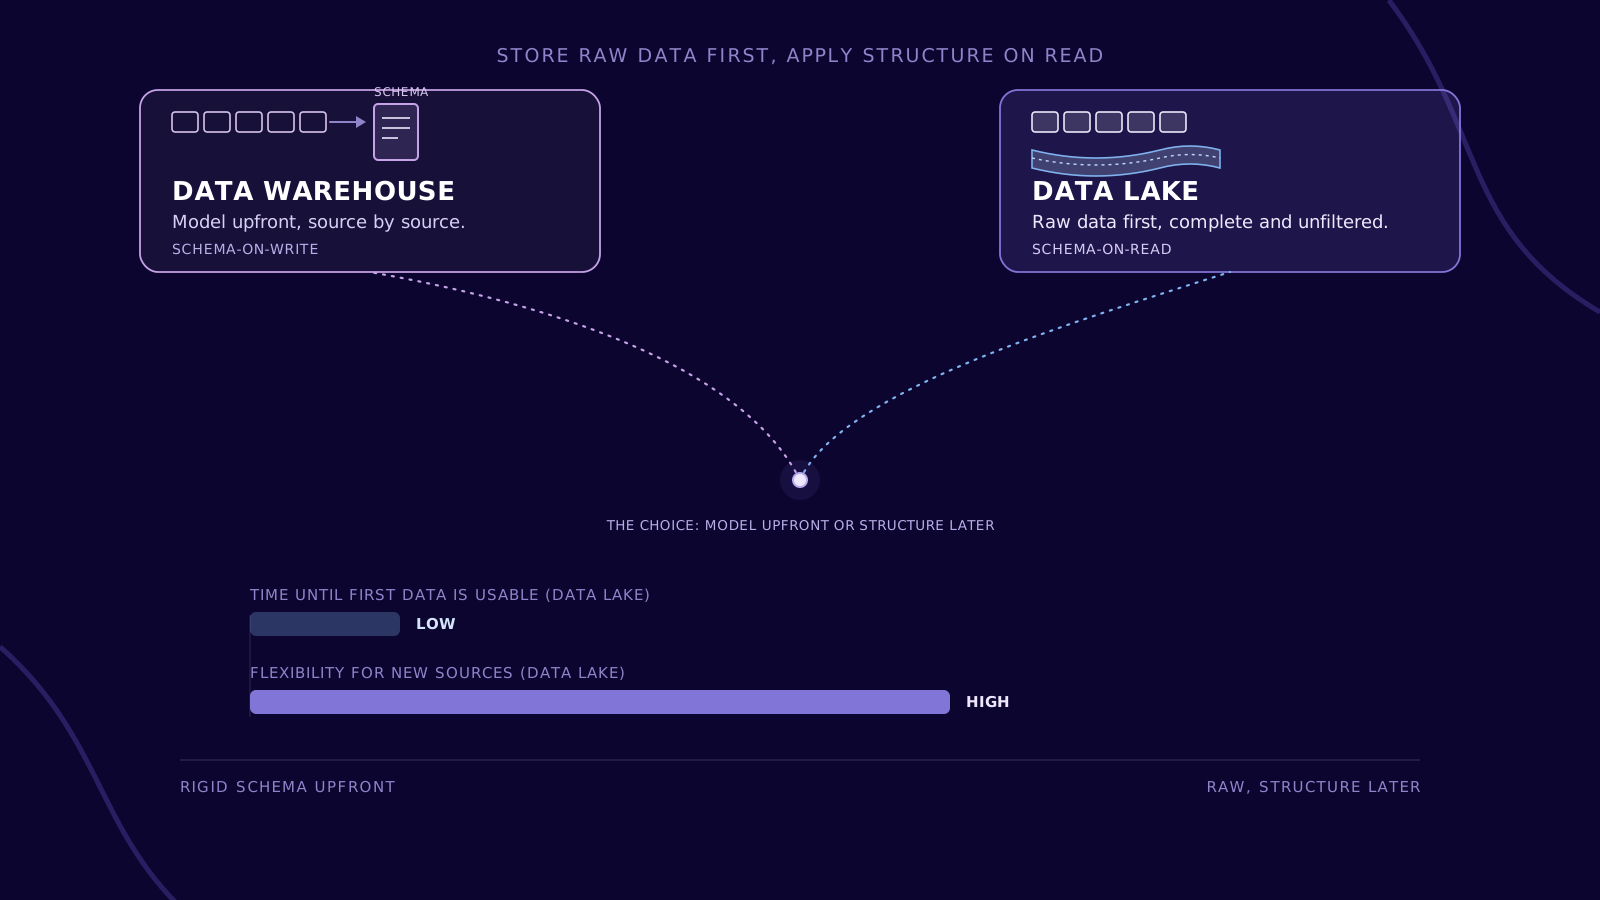
A data lake is a central store that takes in raw data from any source, in its original format — structured, semi-structured, and unstructured side by side. Unlike a data warehouse, it does not enforce a schema on write; structure is only applied on read, depending on the use case. For manufacturing companies, this means machine data, images, logs, and master data all land in one place before it is decided what they will be used for. A data lake is a storage principle, not a finished product.
Definition: Data Lake
The term data lake goes back to a blog post by James Dixon, then Chief Technology Officer at Pentaho, published on 14 October 2010. Dixon contrasted the data mart — refined, filtered, shaped for a single question — with the lake: a large body of water in its natural state, from which everyone draws what they need instead of receiving it pre-bottled.
Technically, a data lake describes a central store that keeps data in its original format — tables, images, log files, free text, and time series side by side, regardless of source. The storage location itself is usually object storage: inexpensive, scalable in practice without limit, and without the structure of a classic file system.
The difference from a data warehouse lies in when structure is applied: a warehouse requires a fixed schema before data arrives (schema-on-write) — every new data source becomes a modeling project. A data lake takes data in raw and only applies a schema on read (schema-on-read) — the question an application asks decides the structure, not a project completed months earlier.
| Trait | Data Warehouse | Data Lake |
|---|---|---|
| Schema | on write (schema-on-write) | on read (schema-on-read) |
| Data types | structured, tabular | structured, semi-structured, unstructured |
| Onboarding new sources | modeling required up front | raw data can be dropped in immediately |
| Typical use | standard reports, fixed metrics | exploration, machine learning, history |
Why raw data comes first
In a manufacturing company, data comes together that follows no shared schema: time series from a controller, inspection images from optical quality control, PDF certificates from suppliers, master data from the ERP system, free text from fault reports. A data warehouse requires a model for each of these sources before the first record arrives — with five sources, that means five modeling projects, none of which can start until it is clear what the data will later be used for.
A data lake reverses the order: data arrives raw and complete, and the question of its structure is deferred until an application actually asks it. This costs little in object storage — cheap enough to also hold data for which there is no use case yet — and it stops a modeling project from becoming a precondition for the first look at the data.
This complements an ordering principle such as the Unified Namespace: a namespace holds the current state of each source, without history. Historical values that it does not retain need somewhere to land — that is exactly the job of the data lake.
How a data lake is structured
A data lake does not prescribe a structure — which is exactly what makes storing everything completely unstructured both tempting and risky. In practice, a layered model has become the standard: it turns raw data into usable data in several stages without losing the original. The most widespread is the medallion architecture, with a bronze, silver, and gold layer — the names come from Databricks’ documentation but are now used across vendors.
| Zone | Content | Audience |
|---|---|---|
| Bronze (raw zone) | data as delivered, unchanged, with origin and timestamp | data engineers, traceability |
| Silver (cleansed zone) | cleaned, deduplicated, typed, merged | business applications, analysts |
| Gold (curated zone) | aggregated, shaped for a specific question | reports, dashboards, machine learning |
The advantage is that each zone can be recomputed independently as long as the raw zone stays unchanged. If a cleansing rule later turns out to be wrong, nothing needs to be re-collected — it is simply re-derived from the bronze zone.
The zone structure in practice
Within each zone, files need a place that can be found again without searching. An ordering by source, plant structure, and time has proven effective — anyone already running a Unified Namespace will recognize the pattern: here too, a naming scheme decided once and modeled on the plant pays off, following the same breakdown as ISA-95 / IEC 62264-1 (Enterprise, Site, Area, Work Center).
A path in the raw zone might look like this:
bronze/north-plant/hall-2/line-3/filler/2026-09-24/sensor-data.parquet
And after cleansing in the silver zone, partitioned by topic instead of by technical origin:
silver/production/temperature/year=2026/month=09/
Three rules have proven useful: partition by the attribute that will most often be filtered on later (usually time); a file name that reveals its origin without an application having to parse it; and a metadata catalog that documents this structure — without it, the tidiest structure is only known for as long as the person who built it stays around.
Object storage, Parquet, Iceberg — what a data lake technically runs on
Three layers carry a data lake in practice:
- Object storage as the foundation: S3-compatible storage systems keep files in a flat layout, without the size limits and upkeep of a classic file server.
- Apache Parquet as the file format: a columnar format from the Apache Software Foundation that reads only the columns actually needed instead of whole rows. A table with 200 columns, of which an analysis needs ten, reads one twentieth of the data — not twenty times as much, as a row-oriented format would.
- Open table formats such as Apache Iceberg, Delta Lake, or Apache Hudi sit on top of Parquet files and add what plain object storage cannot: schema changes without rewriting all the data, time travel to an earlier state, and transactional safety for concurrent writes. A data lake built on one of these formats is often called a lakehouse in the literature — a data lake with the transactional guarantees of a data warehouse.
None of these components on their own turns a data folder into a data lake. That is the job of the metadata catalog: a directory that records, for every table and file, where it came from, what schema it has, who owns it, and how current it is. Without a catalog, there is no way to tell whether a folder is empty because there is no data, or because no one remembers it exists.
Four steps to a data lake
-
Define zones and ownership
Bronze, silver, gold — or a variant of it — get named, and each zone has a clear owner. This is the decision that is most expensive to change later.
-
Connect raw sources
Sources publish into the bronze zone unchanged — no transformation, no pre-filtering. What never arrives can never be re-derived later.
-
Cleanse and catalog
Duplicates, faulty values, and inconsistent formats are corrected in the silver zone, and every table is registered in the metadata catalog.
-
Curate for applications
Gold tables emerge from the silver zone for a specific purpose — a report, a dashboard, a training dataset. A new use case gets a new gold table, not a new export from the source.
What a data lake is not
- Not a data warehouse. It does not replace standard reports built on a fixed structure — for those, a warehouse or a warehouse-style gold zone remains the better choice.
- Not a substitute for real-time systems. A data lake reads historical records, not a millisecond reaction from a machine. That remains the job of controllers, an MES, or a namespace such as the Unified Namespace.
- Not something that runs itself. Without zones, a catalog, and clear ownership, no data lake emerges — only a folder that everything flows into and nothing finds its way back out of.
- Not a product. There is no software whose installation creates a data lake — only software that carries a zone structure and a catalog well or poorly.
Common pitfalls in practice
As early as 2014, the analyst firm Gartner warned in a press release about the “data lake fallacy” — the assumption that storage alone already creates value. Without governance, a data lake turns into a data swamp: a store where data sits, but no one can say any longer which of it is trustworthy, current, or even still in use. The warning is now over a decade old and, in practice, remains the most common reason data lake initiatives fail.
- Missing or stale catalog. Tables without an entry are created faster than they are maintained — and untraceable to anyone within a year.
- Raw zone queried directly. Letting business applications query the bronze zone instead of silver or gold spreads cleansing logic across every application separately.
- No lifecycle. Without rules for when raw data is archived or deleted, storage grows without limit — and so does the clutter.
- Unclear ownership. A zone with no owner does not get operated, only patched when something is noticed.
A data lake does not pay off for every starting position. With a handful of well-structured sources and a fixed set of reports, a classic data warehouse achieves the same with less effort. And without at least one person maintaining zones and catalog over time, no data lake emerges — only the data swamp Gartner already warned about back in 2014.
How pronubes supports a data lake
pronubes is the platform between the shop floor and IT. It captures production data securely, normalizes it, and brings it into a shared structure — then feeds decisions back into the processes as setpoints.
- pronubes Edge collects raw data at the source, buffers it through connection loss, and publishes it unchanged into the raw zone.
- pronubes Zones maps the zone and plant structure — the same naming used by the Unified Namespace is maintained centrally instead of scattered across documents.
- pronubes Insights makes the catalog and data quality visible: which table is how current, and where cleansing is still outstanding.
That keeps the data lake from becoming just a folder, and turns it into an operated part of the landscape. More on the platform
- Data Lake
- Central store for raw data in its original format, with structure applied only on read (schema-on-read).
- Data Warehouse
- Store with a fixed schema on write, built for recurring standard reports.
- Lakehouse
- A data lake with an open table format that adds the transactional safety and schema evolution of a data warehouse.
- Object Storage
- Flat, S3-compatible storage for files of any size and type, without a file-system hierarchy.
- Apache Parquet
- Columnar file format from the Apache Software Foundation for efficient analysis of large datasets.
- Medallion Architecture
- Layered model of bronze, silver, and gold zones that turns raw data into usable data in stages.
- Data Swamp
- An ungoverned, uncataloged data lake in which data can no longer be found or trusted.
Frequently asked questions
Is a data lake the same thing as cloud storage?
No. Storage is only the foundation. A data lake only emerges through zones, a maintained schema per zone, and a metadata catalog — object storage without these three elements is a folder, not a data lake.
Do I need Hadoop for a data lake?
No, not anymore. The term originated in 2010 in the context of Hadoop, but today object storage, a file format such as Parquet, and an open table format such as Iceberg or Delta Lake are enough — no Hadoop cluster of your own required.
How is a data lake different from a lakehouse?
A lakehouse is a data lake to which an open table format adds transactional safety, schema changes without rewriting data, and time travel to an earlier state — capabilities classic data lakes did not offer.
How large should the first slice be?
Large enough that one zone is worked through completely — from raw data ingestion to a gold table that is actually used — and small enough to be done in weeks, not quarters.
What happens if no one maintains the zones?
The store keeps filling up, but the cleansing rules go stale, the catalog develops gaps, and no one can say any longer which table can be trusted. The result is the data swamp Gartner already described in 2014.
 Digital Twin in Manufacturing What a data lake supplies so a twin has history Keep reading
 What Is IT/OT Convergence? The underlying question — in case that’s where you started Keep reading
 Data-Driven Decision Making What a single source of truth changes day to day Keep reading
A data lake that still holds up at the second use case.
30 minutes on your data landscape: which sources exist, how the zones should look, and where data lakes fail in practice.
pronubes is a product of inray Industriesoftware GmbH. Over 30 years of industrial software made in Germany. Innovative and reliable for manufacturing companies.