Time series, native, no detour
What the connection in pronubes brings you.
pronubes Edge writes measured values directly into InfluxDB 3 and queries them again via SQL or InfluxQL, natively and entirely without programming. Three typical applications at a glance.
History for dashboards
Archive and display measured values
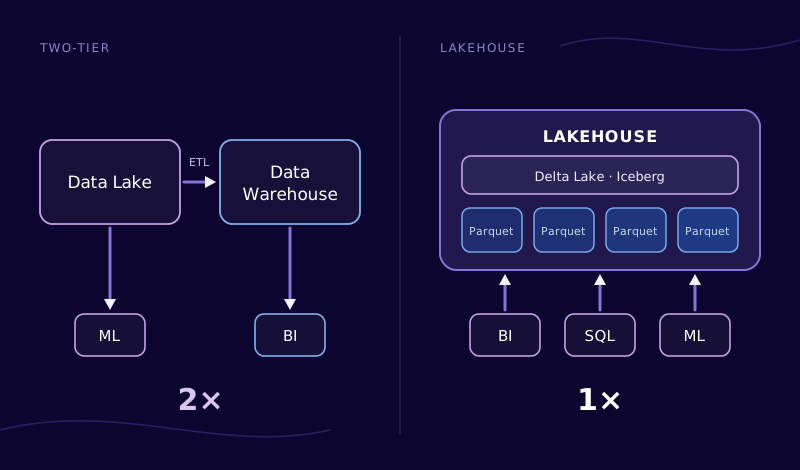
Measured values land natively in InfluxDB 3 and go from there to dashboards. You do not have to program interfaces for this.
History as a source for MES and ERP
Reuse archived values
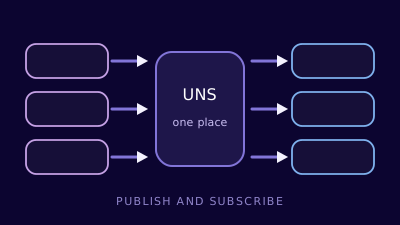
Archived values go to MES, ERP or dashboards without you having to program interfaces. This makes the history a source for these systems.
Large streams of measured values
Fast even with floods of data
Even large streams of measured values can be written quickly if you batch them in the background on request.
Good to know
Plainly said: prerequisites and limits
Time to get your production data moving
In a short conversation, we show you where these updates give you the most leverage in your system landscape.
FAQs
Which InfluxDB editions are supported?
InfluxDB 3 Core and Enterprise are supported natively. For Cloud Serverless and Cloud Dedicated, the previous connector via the v2 API remains.
How do I query data?
Via SQL or InfluxQL, natively and without programming.
Should I use batched writing?
It is optional, and large streams of measured values can be written quickly with it. It cannot be combined with Store & Forward, and if writing fails, batched values are lost.
Where do archived values go?
They go to MES, ERP or dashboards without you having to program interfaces.