From the shop floor to the lakehouse
What the connection in pronubes brings you.
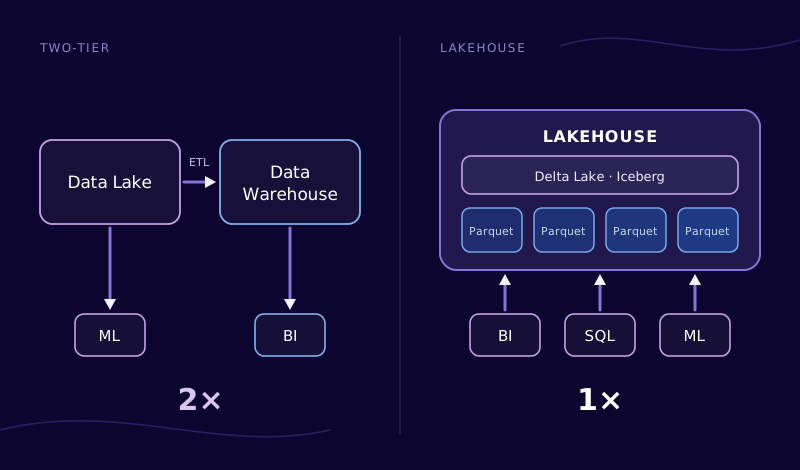
Machine and process data from OPC UA, MQTT, PLCs and SAP flows into Databricks or your own Spark cluster without additional middleware. Three typical applications at a glance.
AI and ML on current production data
Feed models with data from your plant
Machine and process data is loaded continuously into the lakehouse or your Spark cluster. AI/ML then works on current production data.
Analytics and reporting
Reports on continuously loaded data
Analytics and reporting use production data that arrives continuously in Databricks or Spark. You set up the connection like any database connector.
Results back towards production
The loop closes
Predictions, setpoints and master data from the lakehouse return in a controlled way towards production through a configured flow.
Good to know
Plainly said: prerequisites and limits
Time to get your production data moving
In a short conversation, we show you where these updates give you the most leverage in your system landscape.
FAQs
Do I need programming or SQL skills?
No. You set up the connection like any database connector, entirely without SQL knowledge. pronubes Edge uses its own driver, no Java runtime is required.
Which data can I send to Databricks or Spark?
Machine and process data from OPC UA, MQTT, PLCs and SAP flows goes into Databricks or your own Spark cluster without additional middleware.
Can results return to production?
Yes. Predictions, setpoints and master data from the lakehouse return in a controlled way towards production through a configured flow.
Are there limitations?
Yes. The native Windows installation of pronubes Edge is currently a preview, update and delete only work on Delta tables, Kerberos only with the “Binary” transport, and complex Spark types arrive as text.