What does high availability mean in industry?
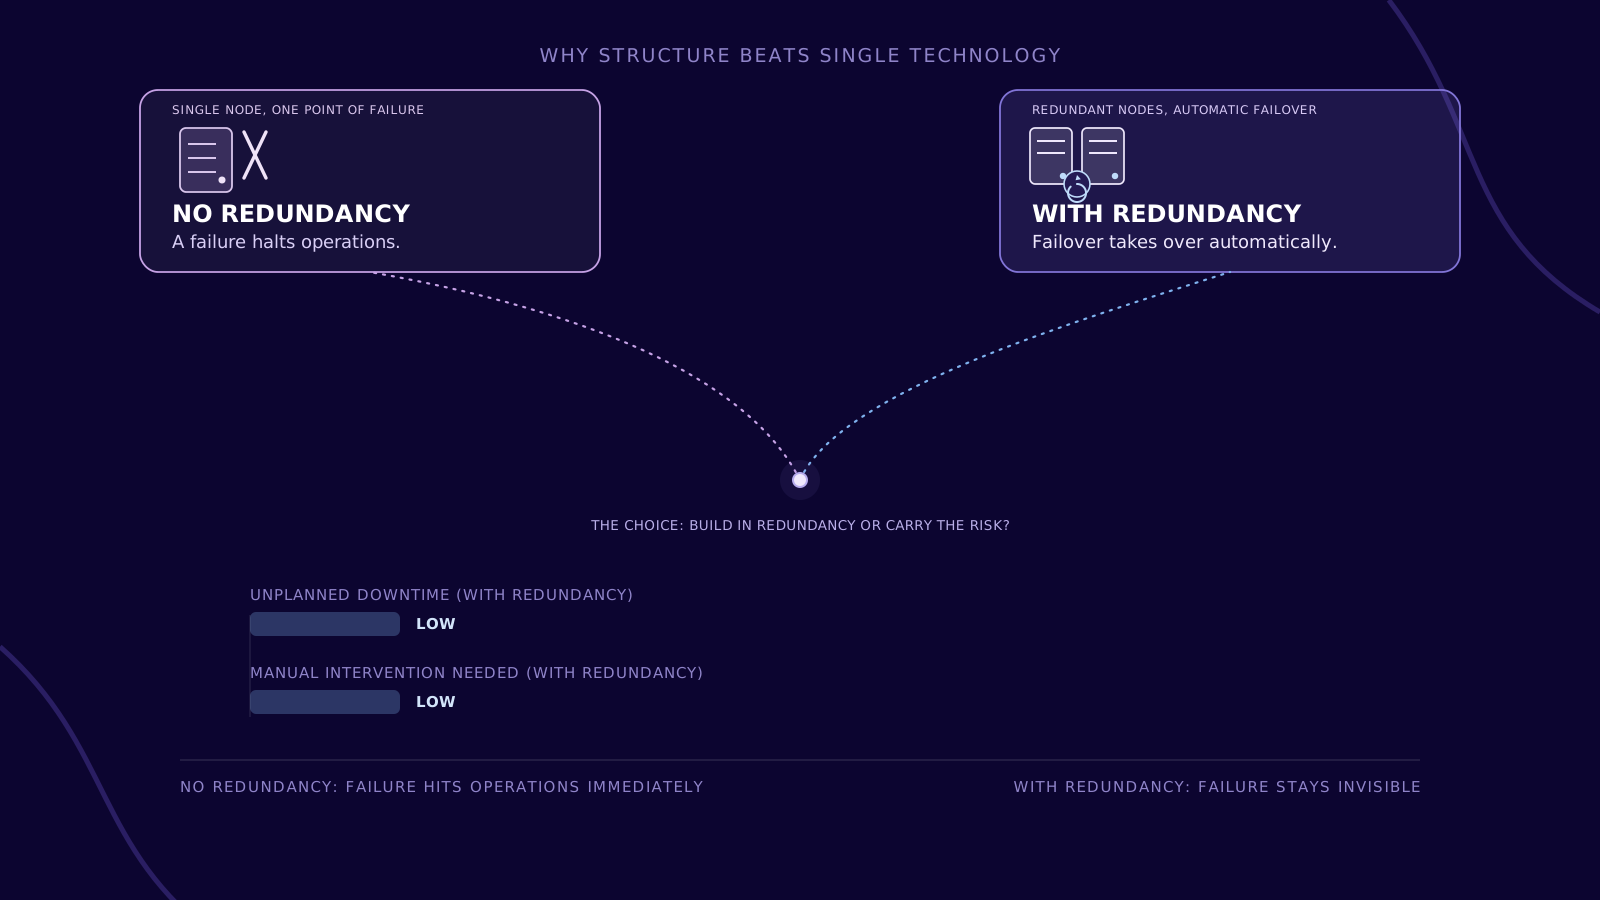
High availability means IT systems absorb failures before they become noticeable in operations. It results from the interplay of redundancy, automated failover and load balancing — embedded in a transparent, well-monitored operation. For manufacturing companies, that means: disruptions stay invisible instead of threatening productivity, revenue, and customer trust.
High availability as a business necessity
High availability is no longer a purely technical discipline — it is a central factor for business success. As soon as IT systems fail, processes stall, employees can't work, and customers quickly lose trust. In many manufacturing companies, IT has long been the backbone of the entire business model.
For CIOs this means: availability directly determines productivity, revenue, and reputation. High availability ensures that disruptions don't become immediately noticeable, keeping the business capable of acting even when something isn't going to plan behind the scenes.
Technical foundation: redundancy, failover, load balancing
At its core, high availability rests on clear principles. Redundancy ensures critical components don't become a single point of failure. Automated failover mechanisms take over tasks without IT teams having to intervene under time pressure. This is complemented by load balancing, which distributes load evenly across systems while improving both performance and availability.
What matters is not any single technology, but how all components work together within a clean architecture.
Examples from practice
MES and SCADA clusters with hot standby: if the active node fails, a second node takes over within seconds, without halting production.
Database replication across two data centers: production data is mirrored synchronously or near-synchronously, so a site failure doesn't cost any data.
Load balancers in front of the web and API layer: requests are distributed across multiple instances, so a single overloaded or failed server doesn't bring things down.
Redundant network paths: between shop floor, control room, and data center, two independent connections ensure that a cable or switch failure doesn't interrupt communication.
Operations, transparency, and control
High availability doesn't end with architecture design. Only in day-to-day operations does it become clear how stable systems really are. Continuous monitoring creates transparency about the state of all critical components and makes it possible to spot deviations early, before they lead to outages.
That reduces escalations and makes maintenance and further development significantly more predictable. Clear operating processes, defined responsibilities, and a high degree of automation matter just as much as the technology itself.
High availability in the cloud era
With cloud and hybrid IT, the focus has shifted: away from individual servers, toward end-to-end services and business processes. CIOs today think in terms of end-to-end availability and rely on distributed architectures to reduce dependencies.
Implemented correctly, high availability becomes more flexible, more scalable, and better aligned with business requirements — an enabler for growth, innovation, and digital resilience.
What high availability is not
Not a replacement for backup and disaster recovery: high availability absorbs short-term failures, but it doesn't replace data backup for a larger incident. Recovery time and recovery point objectives remain separate concerns.
Not an automatic property of the cloud: a cloud provider guarantees the availability of its infrastructure, not the availability of your own application. Without a redundant architecture, a cloud workload remains a single point of failure.
Not a one-time project: architecture, monitoring, and failover tests need continuous upkeep. Build high availability once and leave it alone, and it erodes with every system change.
Typical obstacles in practice
Legacy systems without clustering capability: many long-grown plants and applications were never designed for redundancy and can only be retrofitted with significant effort.
Cost-benefit trade-offs: full redundancy costs money. What matters is identifying critical components and investing in availability where a failure would actually hurt.
Missing failover tests: a failover that has never been tested often doesn't work when it matters. Regular testing belongs to the concept just as much as the technology itself.
Unclear responsibilities: IT and the business side need clarity on who decides what during an incident — otherwise coordination costs more time than the technical failover itself.
How pronubes supports high availability
High availability is a strategic leadership task. CIOs who look at architecture, operations, real-world examples, and typical obstacles holistically build a stable foundation for reliable IT operations and a future-proof corporate IT landscape.
pronubes supports this with redundant architectures, end-to-end monitoring, and clear operating processes — tailored to the requirements of manufacturing companies.
Downtime you plan for, instead of downtime that catches you off guard.
30 minutes on your system landscape: where redundancy is missing today, how to build high availability cleanly, and where it typically fails in practice.
pronubes is a product of inray Industriesoftware GmbH. Over 30 years of industrial software from Germany. Innovative and reliable for manufacturing companies.